Deterministic Prompts: How to Reduce LLM Output Variance
Discover how to reduce LLM output variance using deterministic prompts. Learn about temperature, top-p, and chain-of-thought techniques for consistent AI responses.
Discover how to reduce LLM output variance using deterministic prompts. Learn about temperature, top-p, and chain-of-thought techniques for consistent AI responses.
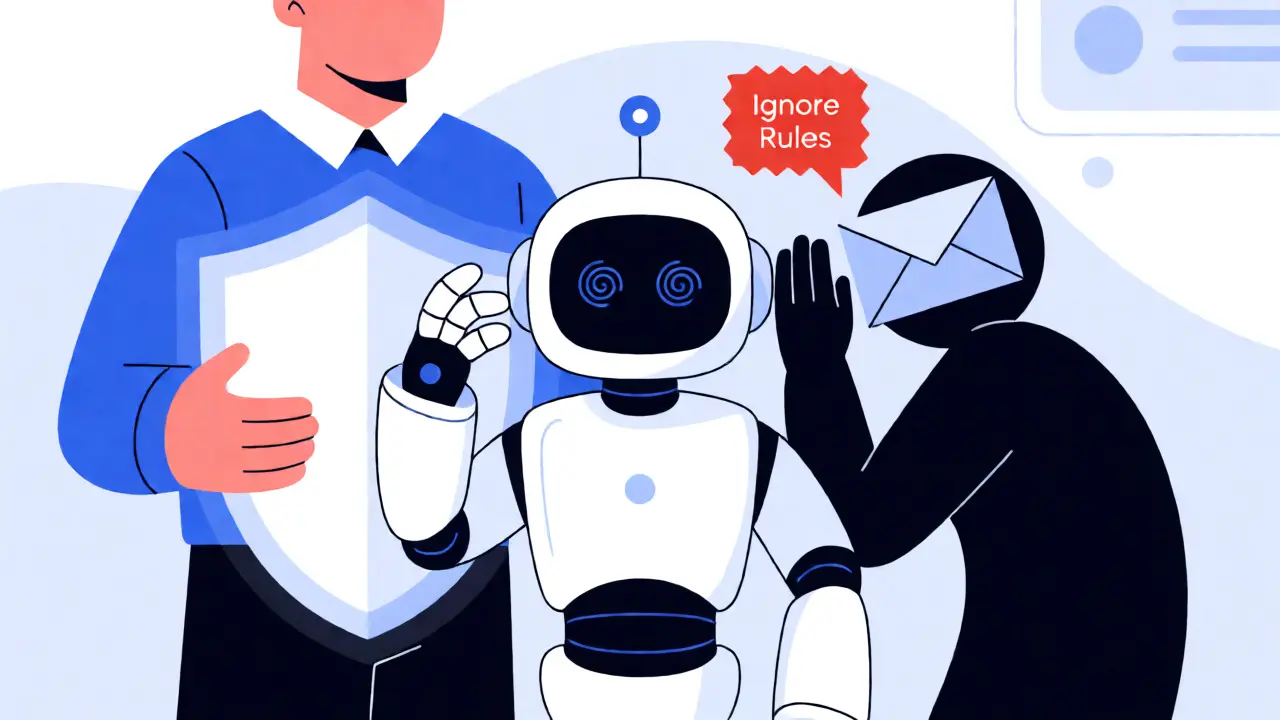
Discover how instruction hierarchies protect AI from prompt injection by prioritizing system rules over user inputs. Learn about OpenAI's breakthroughs and future trends.
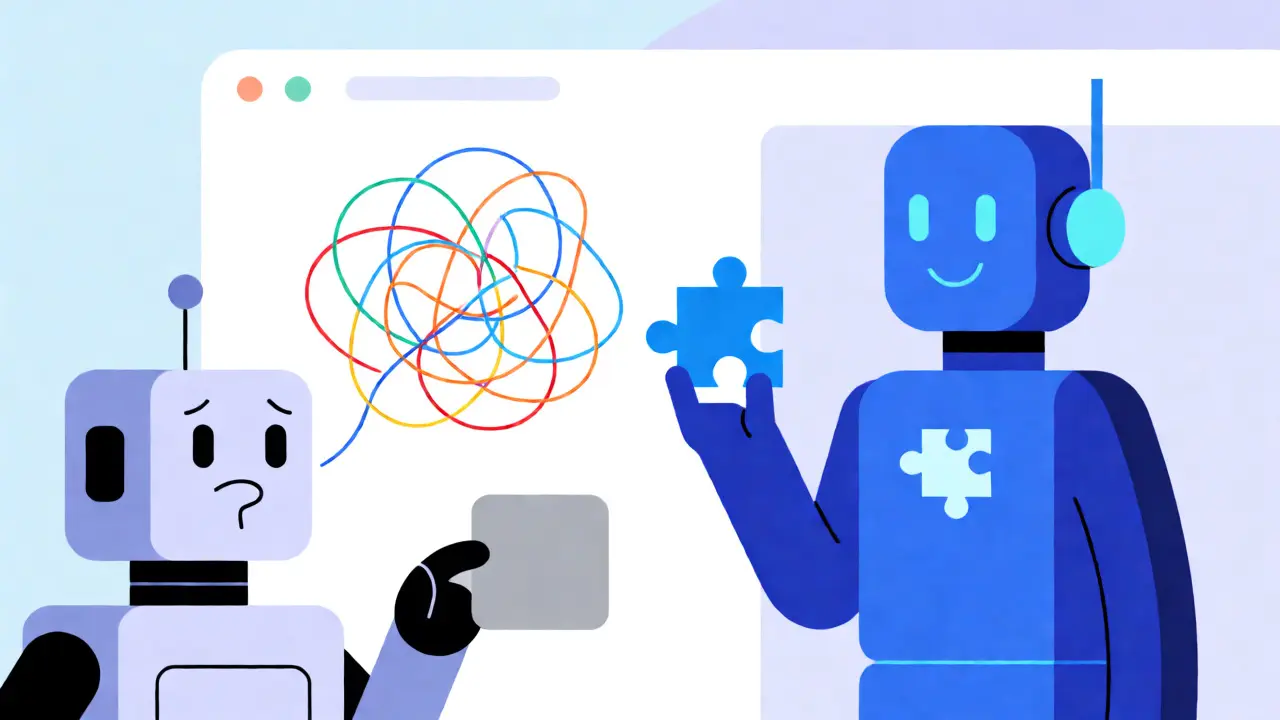
Discover how instruction-optimized transformer variants enhance LLM alignment. Learn about DeMoRecon, DPO, and AlignEZ for better instruction following.
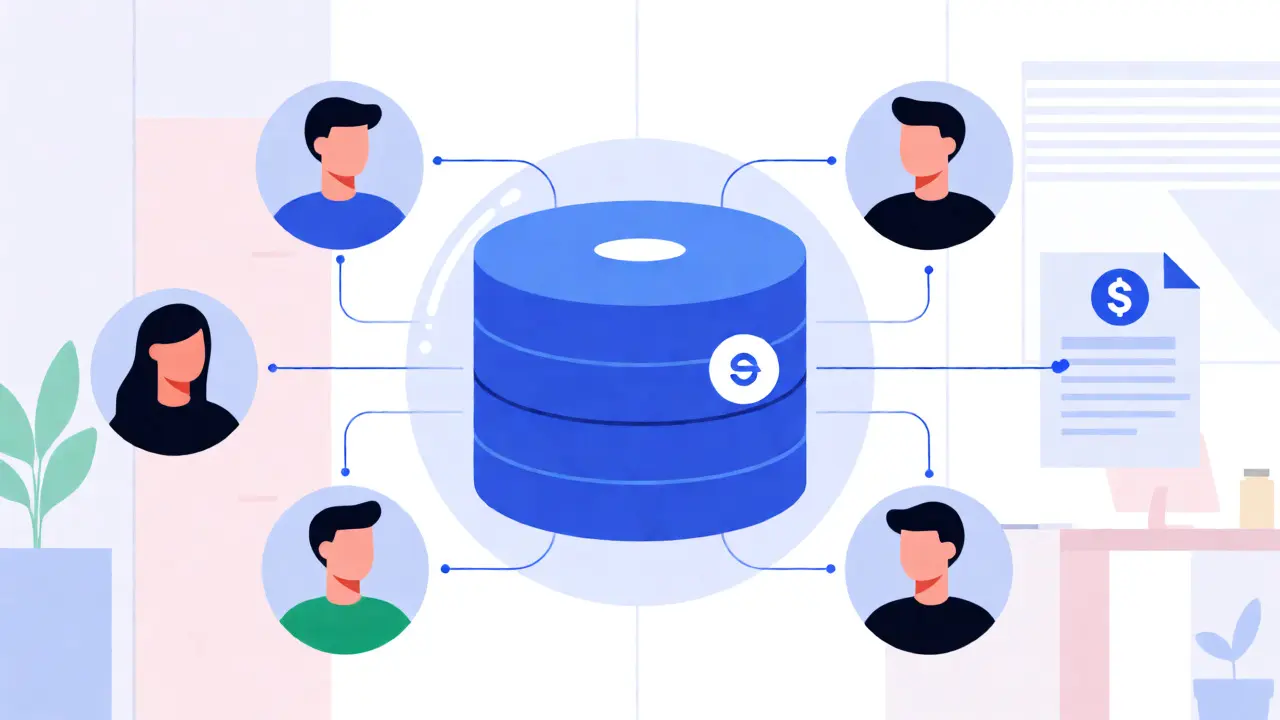
Learn how to secure RAG systems with row-level security and data redaction. Prevent data leaks by filtering vector searches and masking PII before it reaches the LLM.
Discover how to implement a 'guilty until proven secure' policy for AI-generated code. Learn to balance AI productivity with robust security controls.