Streaming vs Batch AI Responses: Accuracy, Latency, and UX
Discover how streaming versus batch processing impacts AI accuracy and user experience. Learn why hallucination risks differ between methods and when to choose each approach.
Discover how streaming versus batch processing impacts AI accuracy and user experience. Learn why hallucination risks differ between methods and when to choose each approach.
Discover how residual connections and layer normalization stabilize Large Language Model training. Learn the differences between Pre-LN and Post-LN, common pitfalls, and best practices for building deep, efficient transformer architectures.
Discover how to reduce LLM output variance using deterministic prompts. Learn about temperature, top-p, and chain-of-thought techniques for consistent AI responses.
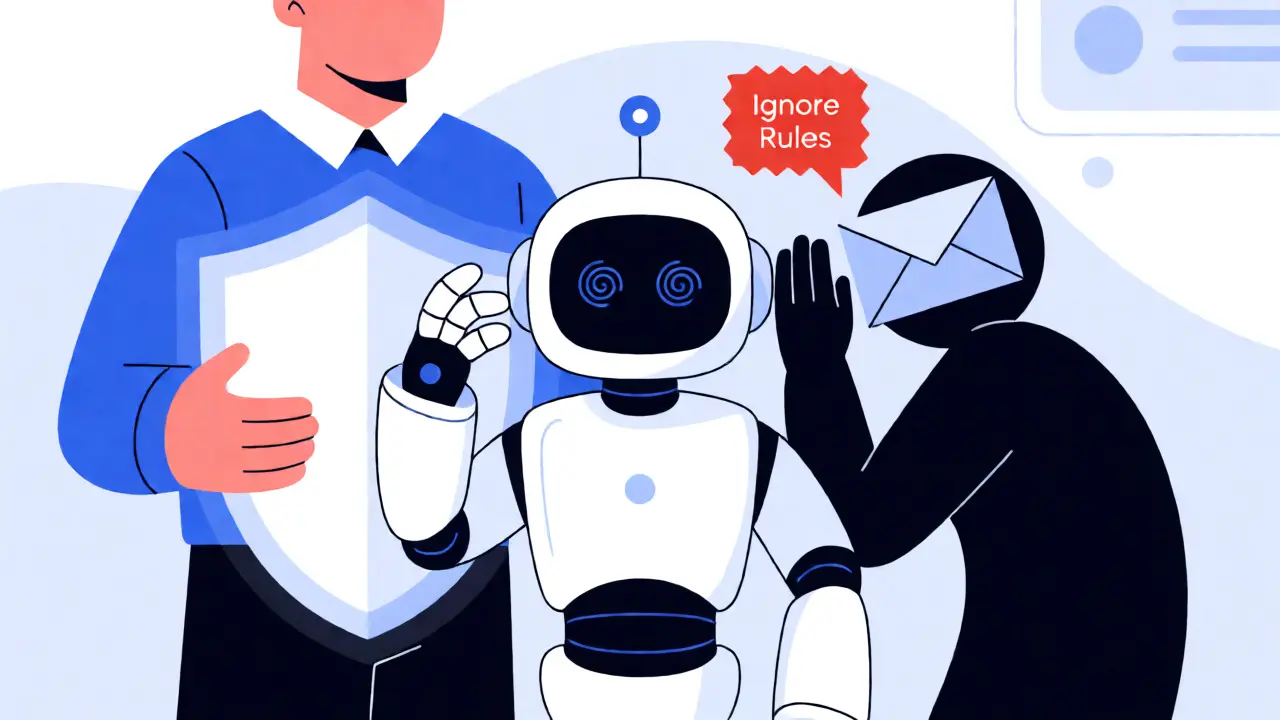
Discover how instruction hierarchies protect AI from prompt injection by prioritizing system rules over user inputs. Learn about OpenAI's breakthroughs and future trends.
Discover how instruction-optimized transformer variants enhance LLM alignment. Learn about DeMoRecon, DPO, and AlignEZ for better instruction following.
Learn how to secure RAG systems with row-level security and data redaction. Prevent data leaks by filtering vector searches and masking PII before it reaches the LLM.
Discover how to implement a 'guilty until proven secure' policy for AI-generated code. Learn to balance AI productivity with robust security controls.