Layer Dropping and Early Exit: Speeding Up LLM Inference
 Nov, 22 2026
You know that feeling when you ask a chatbot a simple question like "What's the capital of France?" and it takes two seconds to answer? That delay isn't just annoying; in high-volume applications, it costs real money. Large Language Models (LLMs) are powerful, but they are also computationally heavy. Every single word you generate forces the model to process information through dozens, sometimes hundreds, of layers. But here’s the thing: not every word needs that much brainpower. "The" doesn’t need deep reasoning. "Paris" doesn’t either. Yet, standard models treat them exactly like complex philosophical queries.
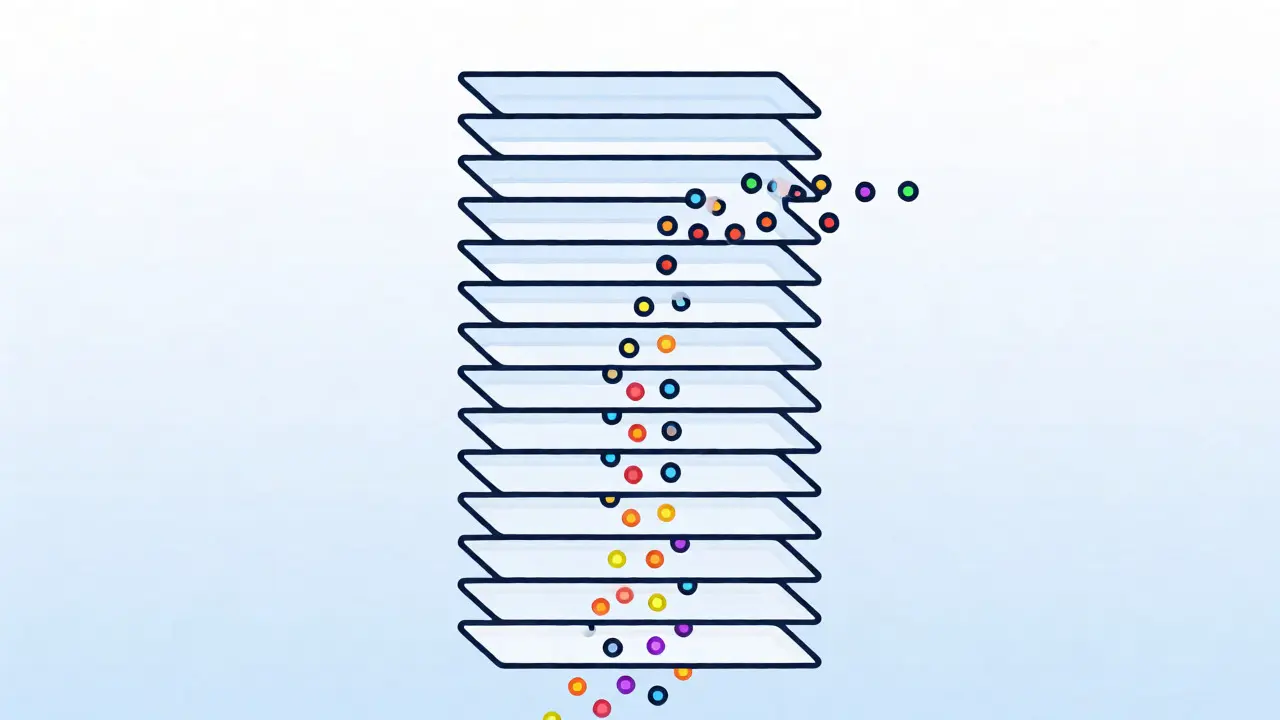
This is where layer dropping and early exit techniques come in. These methods let the model skip work it doesn’t need to do. Instead of running every token through all 32 or 80 layers of a transformer, the model can decide mid-way that it’s confident enough in its prediction and stop processing. Think of it like a student who knows the answer to a math problem after reading the first half of the question-they don’t wait for the teacher to finish explaining the whole chapter. This approach can speed up inference by 1.5x to 3x while keeping accuracy nearly identical to the full model. If you’re deploying LLMs at scale, understanding these techniques isn’t optional anymore; it’s essential for cutting costs and improving user experience.
Why Standard Transformers Are Wasteful
To understand why we need early exits, look at how a standard transformer works. It processes input sequentially through stacked layers. Each layer refines the representation of the tokens. The final layer produces the output probabilities. The problem is redundancy. Research shows that intermediate layers often contain enough information to predict the next token correctly, especially for easy tasks. By forcing every token to go through the entire stack, we waste compute cycles on predictions that were already clear three layers back.
This inefficiency hits hardest in latency-sensitive applications. When you have thousands of users hitting your API simultaneously, those extra milliseconds add up. Traditional optimizations like quantization reduce memory usage but don’t necessarily change the number of operations per token. Layer dropping changes the game by dynamically adjusting the computational depth based on the difficulty of the specific token being processed. It’s adaptive computing for AI.
How Early Exit Mechanisms Work
An early exit mechanism adds lightweight classifiers to intermediate layers of the transformer. During training, the model learns to predict the final output at these checkpoints. During inference, the system checks the confidence score at each checkpoint. If the confidence exceeds a set threshold-say, 95%-the model stops there and outputs the result. If not, it continues to the next layer.
The tricky part is training. You can’t just bolt on exit heads and hope for the best. The model needs to learn that an intermediate prediction should match the final one. Techniques like LayerSkip use a shared loss function across all layers. This ensures that if the model exits early, it’s still making a high-quality prediction. Without this alignment, early exits would lead to garbage outputs. The goal is to make the model "self-aware" of its own uncertainty.
Key Implementations: LayerSkip, EE-LLM, and SLED
Several frameworks have emerged to tackle this problem, each with a different flavor. Let’s break down the big three that are shaping the landscape right now.
| Framework | Core Technique | Speedup Potential | Best Use Case |
|---|---|---|---|
| LayerSkip | Combines layer dropout during training with self-speculative decoding at inference. | 1.5x - 2.5x | General purpose, low-latency chatbots |
| EE-LLM | Integrates early exit modules directly into Megatron-LM pipeline parallelism. | Up to 3x (with batching) | Large-scale enterprise deployments |
| SLED | Selective Layer Extraction for Decoding, reusing projection matrices across layers. | ~2x with accuracy boost | Complex reasoning tasks (math, logic) |
LayerSkip, introduced by Meta AI, is particularly clever because it uses self-speculative decoding. Normally, speculative decoding requires a small draft model to guess tokens for a larger target model. LayerSkip skips the separate draft model. Instead, it uses the earlier layers of the main model as the draft and later layers for verification. This saves massive amounts of memory since you aren’t loading two models. It’s efficient and surprisingly effective for conversational AI where speed is king.
EE-LLM focuses on infrastructure. Built on top of Megatron-LM, it handles the messy details of distributed training. One major hurdle in early exit is batch synchronization. If one sequence in a batch exits at layer 6 and another needs to go to layer 12, the GPU hardware struggles with divergent execution paths. EE-LLM optimizes this using 3D parallelism, allowing it to leverage idle resources effectively. It’s heavier to implement but necessary for huge clusters.
SLED from Google Research takes a different angle. It argues that we shouldn’t just discard intermediate layers; we should combine their insights. SLED reuses the final projection matrix across all layers to create probability distributions, then weights them intelligently. Surprisingly, this can actually improve accuracy. In some cases, intermediate layers catch errors that the final layer misses, such as confusing multiplication signs with equals signs in math problems. It’s a rare win-win: faster and smarter.
The Batch Synchronization Bottleneck
Here is the dirty secret of early exit techniques: GPUs hate divergence. Modern accelerators like NVIDIA H100s thrive on uniformity. They want every thread doing the same thing at the same time. When you have a batch of 32 sequences, and one exits at layer 5 while another goes to layer 20, the hardware has to handle the longest path for everyone. This is known as the batch uniformity problem.
In practice, this limits your theoretical speedups. You might calculate a 3x speedup on paper, but in a heterogeneous workload, you might only see 1.8x. Why? Because the slowest member of the batch dictates the completion time. To mitigate this, some systems group similar tokens together or use dynamic batching strategies that sort inputs by predicted complexity before sending them to the GPU. It’s a logistical challenge as much as a mathematical one.
Implementing Early Exits in Your Stack
If you’re ready to try this, don’t start with your production cluster. Start small. Here is a practical roadmap:
- Choose your framework: If you are already using Megatron-LM, EE-LLM is the natural choice. For PyTorch-based research, LayerSkip implementations are becoming more accessible via open-source repos.
- Set the confidence threshold: This is your primary tuning knob. A threshold of 0.95 is safe but offers modest speedups. Drop it to 0.8 for aggressive speed gains, but monitor accuracy closely. There is no universal "best" number; it depends on your tolerance for error.
- Warm up the exit heads: New exit layers need training. Most frameworks require a warm-up phase (often around 1,000 iterations) where the exit loss weight gradually increases. Skipping this leads to unstable convergence.
- Monitor latency percentiles: Don’t just look at average latency. Look at P99. Early exits help averages, but outliers can still ruin user experience if the batch sync issue bites you.
Be prepared for added complexity. Adding exit heads means adding parameters-usually 10-15% more than the base model. You also need to modify your inference server to handle variable-length computation graphs. If you’re using vLLM or TGI, check their latest releases; support for dynamic depth is improving rapidly.
When Not to Use Early Exits
Early exits aren’t a silver bullet. They shine in scenarios with predictable, low-complexity tokens. Chatbots, code autocomplete, and simple Q&A benefit hugely. But what about complex reasoning chains? If you are asking a model to solve a multi-step physics problem, the early layers might lack the context needed for a correct answer. Exiting too early here could lead to hallucinations.
Also, consider security. Researchers at Stanford have noted that manipulated confidence thresholds could introduce new attack vectors. An adversary might craft inputs that force the model to exit prematurely, bypassing safety filters located in deeper layers. Always test adversarial robustness if you deploy this in customer-facing apps.
The Future of Adaptive Inference
We are moving toward models that know when to think hard and when to coast. Gartner predicts that by 2026, 70% of enterprise LLM deployments will use dynamic computation techniques. We are already seeing second-generation approaches that adjust weighting based on input complexity dynamically, rather than using static thresholds.
For developers, the takeaway is clear: optimize for efficiency without sacrificing quality. Layer dropping and early exit are mature enough for production use today. They offer a tangible way to reduce cloud bills and improve responsiveness. As hardware evolves and software frameworks better handle batch divergence, these techniques will likely become default features in every major LLM serving platform.
Do early exit techniques always reduce accuracy?
Not necessarily. While most methods trade some accuracy for speed, techniques like Google's SLED can actually improve accuracy. This happens because intermediate layers sometimes capture nuances that the final layer overlooks, especially in structured tasks like math or coding.
What is the main bottleneck for early exit in large batches?
The batch synchronization problem. GPUs perform best when all threads execute the same instructions. If sequences in a batch exit at different layers, the hardware must wait for the deepest path to complete, limiting the overall speedup despite individual sequences finishing early.
How does LayerSkip differ from standard speculative decoding?
Standard speculative decoding uses a separate, smaller model to draft tokens for a larger model. LayerSkip uses the earlier layers of the *same* model as the draft and later layers for verification. This eliminates the need to load and manage a second model, significantly reducing memory overhead.
Is implementing EE-LLM difficult for small teams?
It can be challenging. EE-LLM relies on Megatron-LM's complex pipeline parallelism infrastructure. Teams unfamiliar with distributed training frameworks may face a steep learning curve, potentially adding weeks to deployment timelines compared to simpler PyTorch implementations.
Can I apply early exit to any LLM?
Most modern transformer-based LLMs can be adapted, but it requires retraining or fine-tuning with the exit heads included. You cannot simply add exit heads to a pre-trained model without training them to align with the final output distribution, otherwise, the predictions will be unreliable.