Tool-Use Integration: Fixing LLM Hallucinations with Calculators, Search, and Code
 Nov, 18 2026
You ask a Large Language Model (LLM) to calculate the compound interest on a $10,000 investment over 15 years at 4.5%. It gives you an answer. You check it in Excel. The model is wrong. Why? Because LLMs are not calculators; they are pattern matchers. They predict the next likely word, not the next correct digit. This fundamental limitation leads to factuality control issues that can derail entire applications.
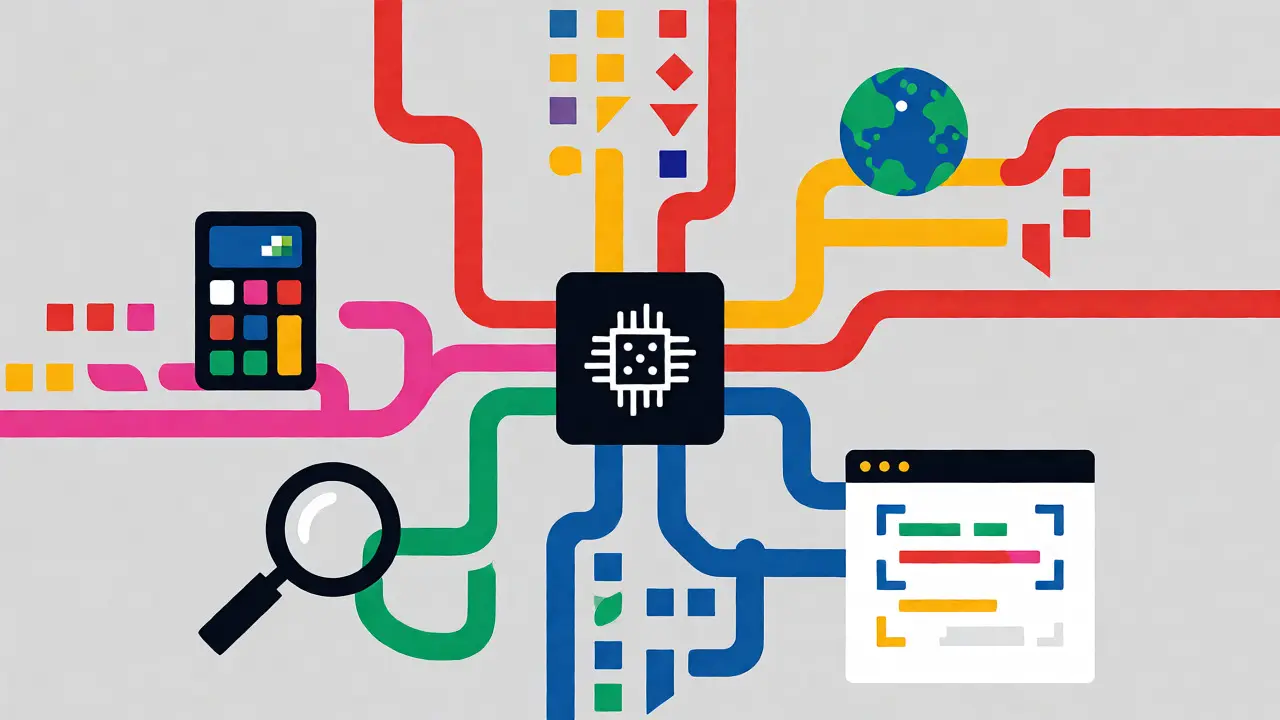
The solution isn't just "better models." It's Tool-Use Integration, which is a method of connecting LLMs to external systems like calculators, search engines, and code interpreters to handle tasks beyond their native capabilities. By offloading specific jobs to specialized tools, you turn a probabilistic text generator into a reliable reasoning engine. Here is how to implement this architecture effectively.
Why Native LLM Reasoning Fails on Precision Tasks
LLMs process information through token prediction. When you ask for a math problem, the model doesn't "do" the math. It retrieves patterns from its training data that look like the answer. For simple arithmetic, this works fine. But as complexity increases-multi-step calculations, large numbers, or real-time data-the error rate spikes. A study by researchers at various institutions has shown that accuracy drops significantly when models attempt mental arithmetic without external aids.
Consider the difference between knowledge and computation. An LLM knows what a stock market index is. It does not know today's closing price unless that price was in its training data, which ends months ago. Without external access, the model hallucinates current events. It guesses. Tool-use integration bridges this gap by separating language understanding from factual retrieval and logical execution.
The Core Tools: Calculators, Search, and Code Execution
Three primary tool categories address most accuracy gaps. Each serves a distinct function in the pipeline.
Code Execution allows the model to write and run Python code in a sandboxed environment. This is the heavy lifter for complex logic. Instead of guessing a statistical average, the model writes a script to fetch data, clean it, and compute the mean. OpenAI’s Code Interpreter and similar features in xAI’s Grok demonstrate this capability. If the code fails, the model reads the error message, fixes the code, and tries again. This iterative debugging loop is crucial for reliability.
Web Search provides real-time information retrieval. Models have a training cutoff date. Web search tools bypass this limit. When you ask, "What is the latest version of Python?", the model shouldn't rely on memory. It should query a search API, read the top results, and synthesize the answer. This ensures your application remains relevant even as the world changes.
Calculator Tools offer lightweight arithmetic precision. While code execution is powerful, it is resource-heavy. For simple addition or percentage calculations, a dedicated calculator tool is faster and cheaper. Anthropic’s Claude platform, for example, supports recipe-based implementations where basic math is routed to a simple calculator rather than spinning up a full Python interpreter.
How the Architecture Works Under the Hood
The magic lies in the orchestration layer. You don't hard-code every interaction. Instead, you define available tools in your API request. The model then decides when to use them.
Here is the typical flow:
- Prompt Reception: The user asks a question requiring external data or calculation.
- Tool Selection: The LLM analyzes the intent. Does it need current news? It selects the search tool. Does it need to analyze a CSV file? It selects code execution.
- Instruction Generation: The model emits a special token or JSON object representing the tool call. For example, it might output
{"tool": "web_search", "query": "current S&P 500 price"}. - External Execution: Your application intercepts this signal, pauses the LLM generation, and executes the actual search or code.
- Result Injection: The result (e.g., "S&P 500 is at 4,500") is fed back into the context window.
- Final Synthesis: The LLM uses this new fact to generate the final natural language response.
This process requires robust handling of both server-side and client-side tools. Providers like xAI allow simultaneous activation of multiple tools. Their SDK supports requests where web_search() gathers data and code_execution() analyzes it in one go. However, if you use custom client-side tools, the execution pauses, returning control to your backend until you provide the result.
Comparing Implementation Strategies
Not all providers handle tool integration the same way. Choosing the right stack depends on your latency requirements and budget.
| Provider/Model | Native Code Execution | Web Search Integration | SDK Support Notes |
|---|---|---|---|
| OpenAI (o3/o4-mini) | Yes (Code Interpreter) | Via plugins or API | Strong support for iterative debugging and file processing. |
| xAI (Grok-4.20) | Yes (Server-side) | Yes (Web + X Search) | Requires xAI SDK; Vercel AI SDK currently lacks advanced tool support. |
| Anthropic (Claude) | Via recipes/tools | Configurable | Focuses on structured tool definitions and safety guidelines. |
A critical pitfall here is SDK compatibility. As of late 2026, many popular frontend frameworks do not fully support advanced agentic loops. For instance, developers using the Vercel AI SDK often find that complex multi-tool workflows require falling back to the provider-specific SDKs (like xAI or OpenAI) to manage the state correctly. Don't assume your high-level framework handles the low-level token streaming of tool calls automatically.
Practical Use Cases and Pitfalls
Where does this actually help? Consider financial analysis. Asking an LLM to "calculate the average P/E ratio of the top 10 tech stocks" without tools yields a hallucinated number. With web search and code execution, the model searches for the current ratios, extracts the numbers, and runs a Python script to compute the average. The result is verifiable.
Another common scenario is sentiment analysis. Combining social media search (like X search) with code execution allows the model to scrape recent tweets, tokenize them, and run a sentiment score algorithm. This transforms vague qualitative answers into quantitative data points.
However, integration introduces new failure modes:
- Latency: Every tool call adds round-trip time. A simple chatbot response might take seconds instead of milliseconds.
- Cost: Code execution environments charge for CPU time. Running inefficient Python scripts repeatedly burns budget.
- Infinite Loops: If the model keeps trying to fix broken code, it may never return a final answer. Implement strict iteration limits.
Best Practices for Reliable Factuality
To maximize accuracy, follow these heuristics:
Force Tool Usage for Math: Never let the model guess numbers. Explicitly prompt it to use the calculator or code interpreter for any operation involving more than two digits.
Validate Inputs: Before executing code, ensure the model isn't trying to delete files or access unauthorized network ports. Sandboxing is non-negotiable.
Cache Results: If you are searching for static facts (like "capital of France"), cache the tool result. Don't hit the search API for every identical query.
Handle Empty Results: What if the web search returns nothing? The model must be trained or prompted to say "I couldn't find that," rather than inventing a plausible-sounding lie.
By treating the LLM as a router rather than an oracle, you build systems that are both creative and accurate. The model handles the nuance of language; the tools handle the rigor of truth.
Why do LLMs make math errors even when they seem smart?
LLMs are trained to predict the next token in a sequence based on probability, not to perform logical deduction or arithmetic. They memorize patterns of how math problems look and sound, but they lack an internal computational engine. As numbers get larger or operations become multi-step, the probability distribution becomes too noisy to guarantee the correct digit sequence, leading to hallucinations.
Is code execution safer than letting the model guess?
Generally, yes, provided it runs in a sandboxed environment. Code execution produces deterministic outputs based on logic, whereas model guessing is probabilistic. However, security risks exist if the sandbox is poorly configured, allowing malicious code to escape. Always isolate execution environments from your main application infrastructure.
Which tools should I prioritize first for my application?
Start with web search if your content needs freshness (news, prices, weather). Add code execution if your users perform data analysis or complex calculations. Calculator tools are useful only if you have extremely high volume of simple arithmetic and want to reduce costs compared to full code interpretation.
Does tool use slow down response times?
Yes, significantly. Each tool call involves stopping generation, making an external API request, waiting for the response, and resuming generation. A single search might add 1-3 seconds. Complex code execution can take longer. Optimize by caching frequent queries and limiting the number of sequential tool calls per user request.
Can LLMs use multiple tools at once?
Modern architectures support parallel or sequential multi-tool usage. For example, a model might trigger a web search to find a dataset URL, then immediately invoke code execution to download and analyze that dataset. Some providers allow simultaneous activation, while others require a step-by-step chain where each tool's output informs the next tool's input.