Transformer Layers in Production LLMs: Memory and Compute Footprints
Master LLM inference costs by understanding transformer layer footprints. Learn how KV cache, quantization, and FlashAttention impact memory and compute in production.
Master LLM inference costs by understanding transformer layer footprints. Learn how KV cache, quantization, and FlashAttention impact memory and compute in production.
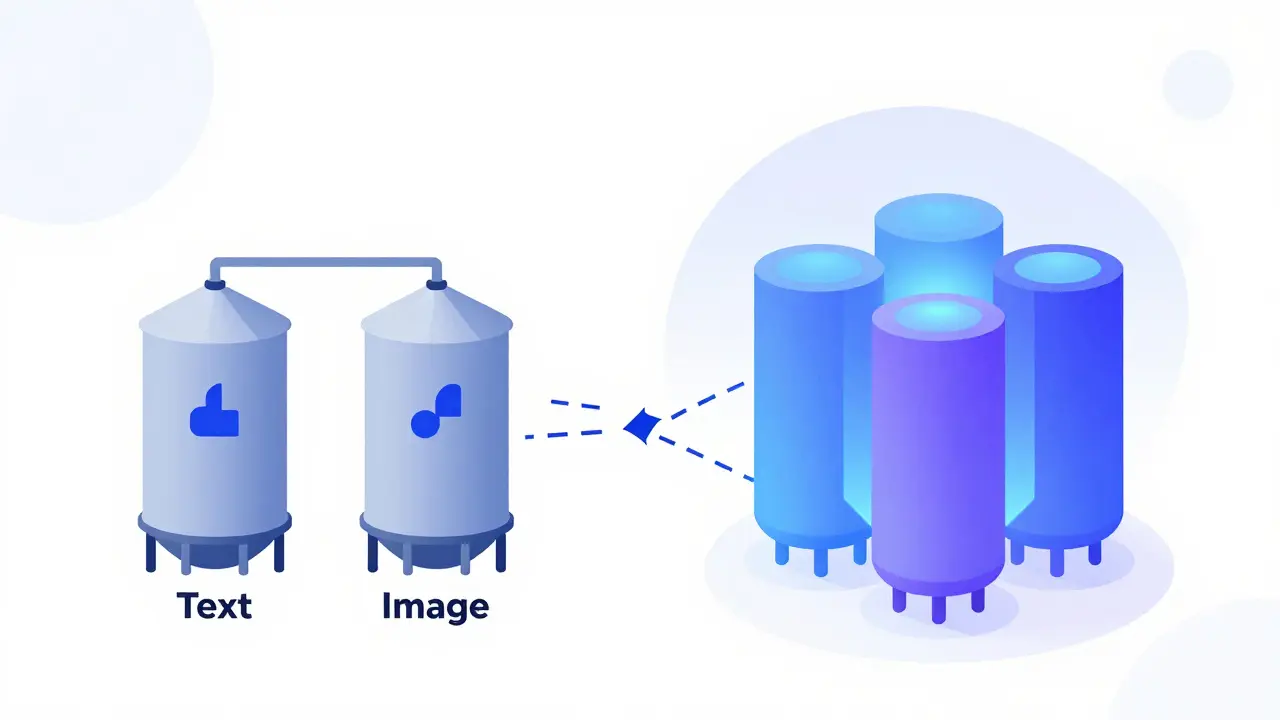
Discover how Vision-Language Transformers unify images and text into a single architecture. Learn about the shift from dual-stream models to unified token processing, key applications like text-to-image generation, and the future of multimodal AI.
Explore how Agentic Generative AI transforms business by executing multi-step workflows autonomously. Learn about the tech, costs, and risks of deploying AI agents in 2026.
Discover how low-latency AI models under 50ms are revolutionizing 'vibe coding' in 2026. Compare Cursor, Tabnine, and local options for maximum flow state.
Learn how to secure vibe-coded backends with robust authentication and authorization patterns. Avoid common AI pitfalls like missing RBAC, insecure JWT configs, and deprecated OAuth flows.
Learn how to secure vibe coding environments with robust access control, data privacy measures, and repository scope management to prevent AI-induced vulnerabilities.
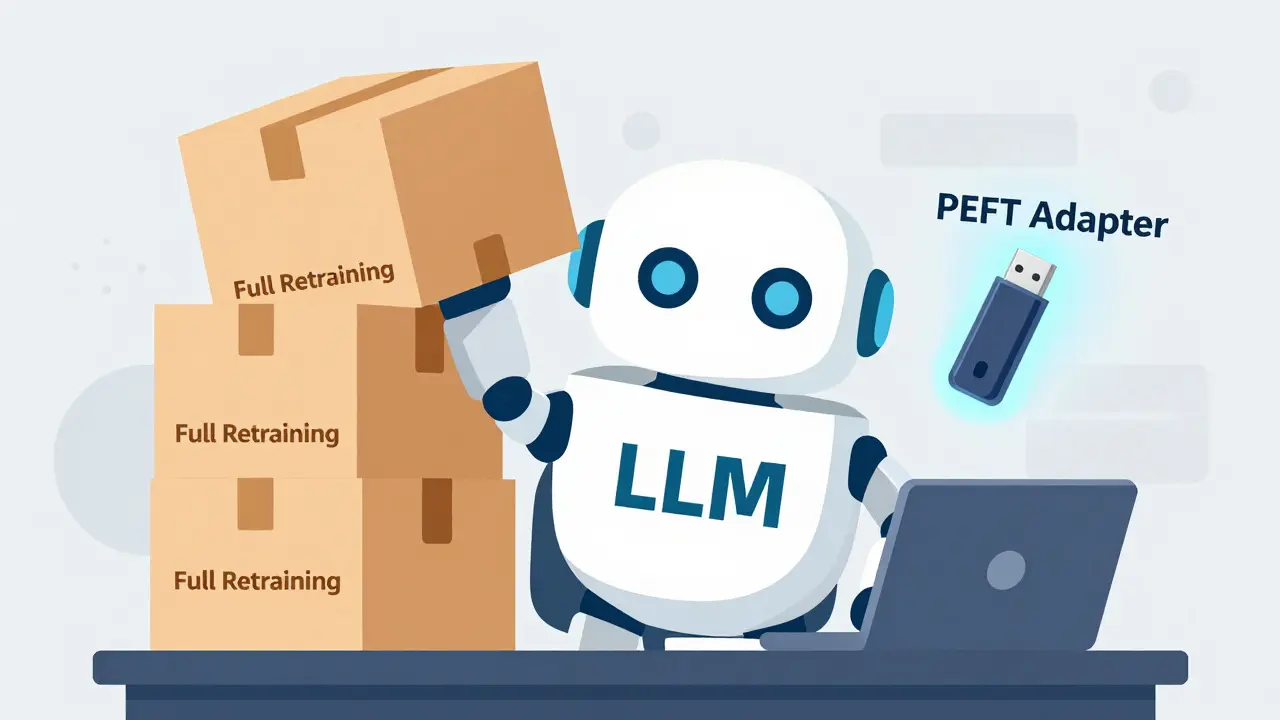
Explore Prefix Tuning and Prompt Tuning, two lightweight PEFT methods for adapting LLMs. Learn how they differ, their implementation details, and why they save compute costs.
Explore how Human-in-the-Loop control ensures safety in LLM agents. Learn about tiered implementation, costs, regulatory requirements, and best practices for 2026.
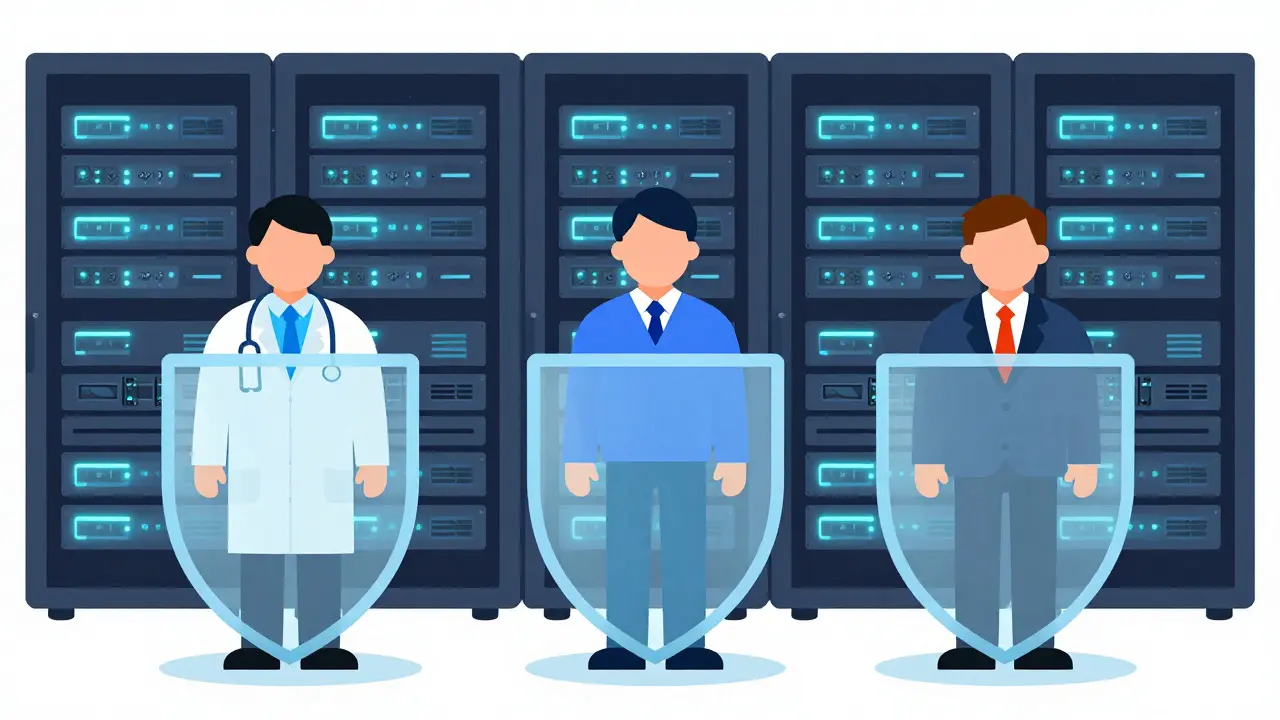
Learn how to secure multi-tenant self-hosted LLMs with effective isolation strategies. Discover best practices for data separation, prompt injection defense, and cost-efficient architecture.
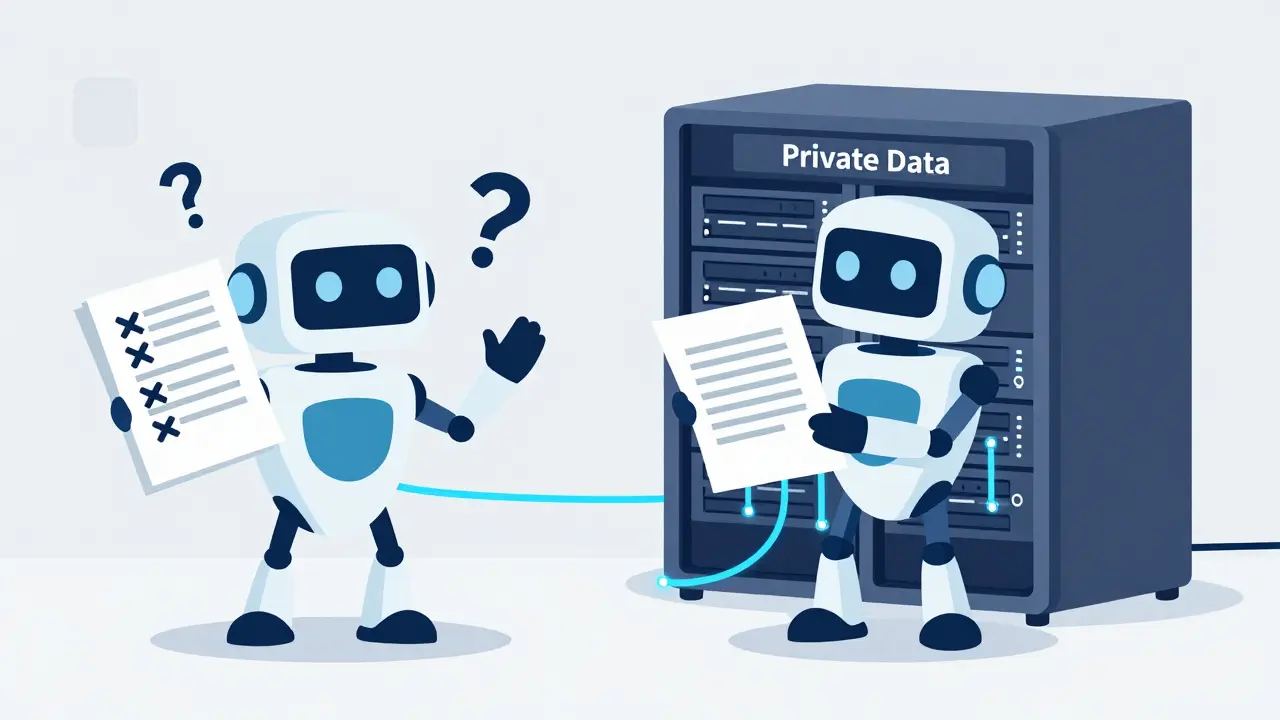
Learn how Retrieval-Augmented Generation (RAG) fixes LLM hallucinations by connecting AI to your private data. This end-to-end guide covers architecture, RAG vs fine-tuning, and implementation tips.
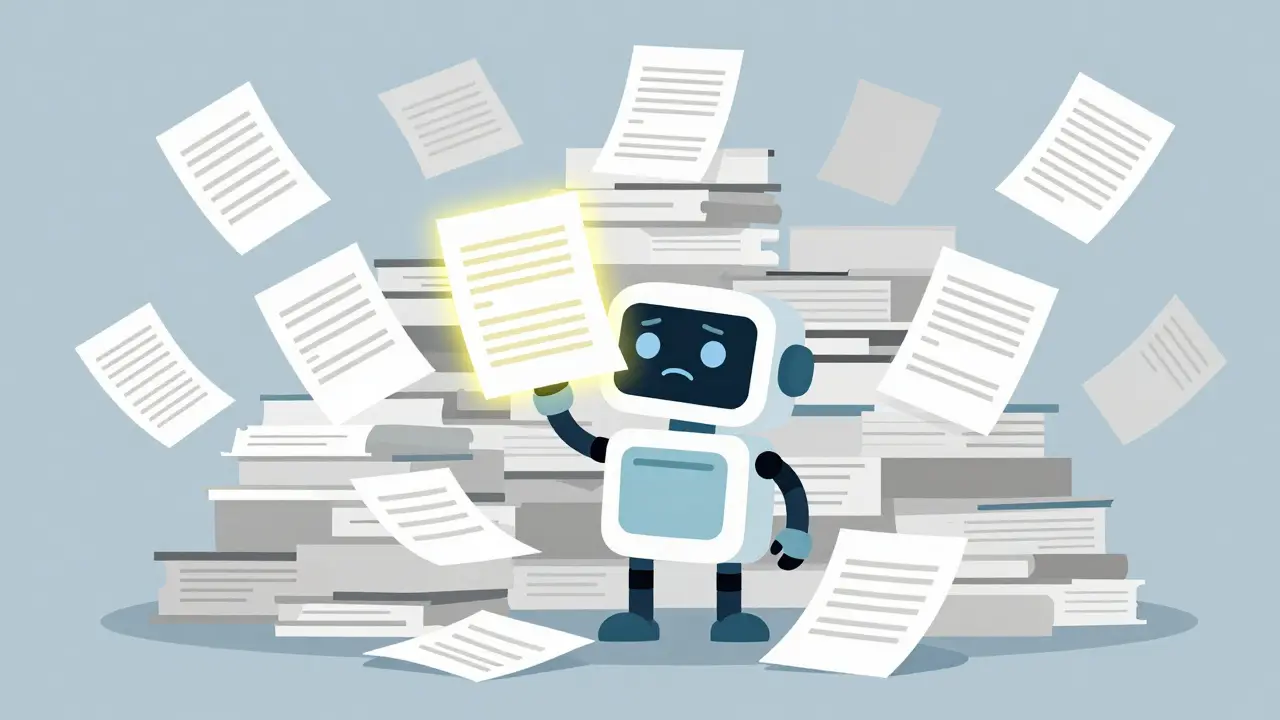
Learn how to fix the 'Lost in the Middle' problem in LLMs. Discover prompt positioning strategies like query-first and bookending to boost accuracy in long-context AI tasks.
Learn how compression-aware prompting optimizes small LLMs by reducing token usage and improving accuracy. Explore tools like LJMLingua and TPC for efficient RAG and inference.